
Primer Designer
Marked experimental: the surface can change.
Design primers against a region of an open sequence and see every number that decides whether they will work — melting temperature under a buffer you state, GC content, and the secondary structures that make primers fail.
| Reached by | Tools → Primer Designer |
| Sample project | Primer test · Colony-PCR verification |
What it does
Two primers that flank your region is the easy part. Nearly any tool will hand you a pair. The hard part is that a pair which looks perfect on paper — right length, right Tm, right GC — can still give you a blank lane or a smear of primer-dimer, and the reasons are almost always structural: the primer folds back on itself, it pairs with a copy of itself, the two primers pair with each other, or its 3-prime end is so stable that it anchors and extends at sites it only partly matches.
So this panel does three things in one pass:
- Enumerates amplicon windows inside your constraints and designs a primer pair for each one, growing each primer until it hits your target melting temperature.
- Measures every candidate: melting temperature, GC, hairpin, self-dimer, 3-prime self-dimer, cross-dimer with its partner, 3-prime end stability, poly-X runs, dinucleotide repeats, the GC clamp, how many places it binds on the template, and whether it hits a repeat library.
- Ranks them under a weighting you can see and change, so the order is a judgement you made rather than one the tool made silently.
The measurements are not ours. They are primer3’s — the same thal thermodynamic-alignment engine
and the same oligodg nearest-neighbour calculation that primer3web and ntthal run — and they are
checked against primer3’s own output before they ship. The ranking is ours, and every weight in it
is a control on screen.
What this computes
Per primer — melting temperature under the buffer you set (nearest-neighbour, the table you choose); GC percent; length; hairpin ΔG; self-dimer ΔG; 3′ self-dimer ΔG; 3′ end stability; the longest poly-X run; the longest dinucleotide repeat; the number of G or C bases in the last five; where the oligo binds the template — every site, on both strands, listed with its coordinates rather than counted, so a primer that anneals twice tells you where the second place is; and, when a repeat library is loaded, its best hit in that library with the percent identity behind it. A sequencing-walk primer is not screened this way, because it is designed against the read it delivers rather than against the whole template, and the panel says so instead of reporting one site.
Per pair — cross-dimer ΔG and 3′ cross-dimer ΔG between the two primers, each with the duplex it
came from; product length; product GC; product melting temperature (Rychlik, Spencer & Rhoads
1990, in the corrected form their 1991 erratum prints), computed at the monovalent cation
concentration of the buffer you set — sodium plus potassium plus half the Tris, the same sum every
other melting temperature here uses, and shown beside the number so you can see which salt answered;
and the suggested annealing temperature, which on the Taq path is
0.3 × the lower primer Tm + 0.7 × the product Tm − 14.9 — so the product melting temperature you
are shown is 70 % of the annealing temperature beside it. A DNA-binding-domain polymerase (Phusion
and relatives) uses a different rule, the lower primer Tm + 3, and does not use the product term at
all; the panel prints the cycling program for both.
Per candidate, as a ranking — a score of 100 − Σ(weight × penalty) over fifteen terms: distance
from your target Tm, the difference between the two primers' Tm, distance from the GC and length
optima, self-dimer, 3′ self-dimer, hairpin, cross-dimer, 3′ cross-dimer, 3′ end stability, poly-X,
dinucleotide repeat, GC clamp, template specificity, and repeat-library mispriming. Every weight is a
control, and each pair shows which terms cost it what, so a rank is a statement you can check rather
than a number to trust. The score is a ranking, not a measurement: it orders candidates under
your weights and carries no units.
What is not estimated — this panel does not predict yield, band intensity, or whether a reaction will work. Specificity here is on the template you have open; a genome-wide answer is a database search, and the panel hands the primer to one rather than approximating it.
When you’d use this
Used in: Clone an insert into a vector, and prove it worked · Design a CRISPR guide, check where else it binds, and measure the edit you got · Design primers, simulate the PCR, and predict the band
- You need to amplify a region and you want the pair that will actually work. This is the default use. Select the region, set a product-size window, design. Then take the winner to PCR Simulation to see the product, and to Digest & Gel to see the band.
- A PCR failed and you want to know whether the primers were the problem. Design against the same region and read the structure numbers on the pair you actually used — a hairpin melting above 24 °C or a 3-prime cross-dimer above 35 °C is a real explanation for a blank lane.
- You are adding a tail — a restriction site, an adapter, a homology arm. Put it in the tails field and every structure number is recomputed on the full oligo, because a tail that anneals to nothing can still fold, and frequently does.
- You need a sequencing walk rather than a pair. The sequencing task tiles forward primers across the region at a spacing you set.
Reach for something else when: you already have the oligos and only want to know where they bind — that is Primer Library, whose Check and Screen tabs test existing primers against your constructs. If you want one melting temperature under many models, that is Melting Temperature. If you are designing a probe-based assay, that is qPCR Design.
Where it lives
Tools → Primer Designer opens it in the right rail. Right-click on the canvas → Primer Designer opens it seeded from the current selection, so a region or feature you have highlighted arrives already loaded as the design target. The designed pair can be written back to the map as primer annotations, opened as a new project containing just the product, or saved into the Primer Library.
Inputs and outputs
In: an open nucleotide sequence, circular or linear. The design target is the whole sequence, the current selection, or bases you paste. Circular templates are handled properly — an amplicon may span the origin.
Out: a ranked table of primer pairs; for each pair, both primer sequences with their binding coordinates and full measurement set, the product sequence, its length and GC, an optimal annealing temperature, an annealing diagram and a suggested cycling program. Pairs export as FASTA or as a CSV carrying every measurement per primer.
What it refuses, and what it tells you. If no pair satisfies your constraints, the panel does
not simply return nothing — it names the constraint that did the rejecting. Designing the tet
CDS of pBR322 as a target:
| What you set | What the panel says |
|---|---|
| Product 300–700 bp | The target cannot sit inside a 700 bp amplicon — a 1,191 bp CDS does not fit |
| Product 1,200–1,500 bp | The GC window rejected them: pBR322 is AT-rich where tet starts, and the only primer reaching there is 36% GC against a 40% floor |
| GC 30–70% | One pair, 1,309 bp, Ta 61.8 °C |
That middle row is the point. The generic advice — “widen the size or Tm window” — is wrong there, and following it wastes an afternoon.
Worked example
Open the Colony-PCR verification sample and stay on the fas2__KanMX4 sequence (3,613 bp).
Open Tools → Primer Designer and design with the panel defaults (new pair, whole sequence, product
300–700 bp, target Tm 60 °C). Five pairs come back. The top one:
| Forward | Reverse | |
|---|---|---|
| Sequence | CAAAAATTACGGCTCCTCGC | ATCGGGCTTCCCATACAATC |
| Binds | 1,275–1,294 | 1,591–1,610 |
| Tm | 60.4 °C | 60.5 °C |
| GC | 50% | 50% |
| 3′ stability | 5.0 kcal/mol | 2.7 kcal/mol |
| Hairpin | −0.1 kcal/mol, melts at 38.1 °C | −0.6 kcal/mol, melts at 46.9 °C |
| Self-dimer | −2.9 kcal/mol | −3.7 kcal/mol |
| 3′ self-dimer | −1.5 kcal/mol | 0.4 kcal/mol |
| Binding sites | 1 | 1 |
Product 336 bp, 46.4% GC, optimal annealing temperature 57.1 °C. Score 95.5 of 100.
Read the warnings under it rather than the score: both hairpins melt above primer3’s 24 °C limit (38.1 °C and 46.9 °C), and the panel says so in those words. The pair is still the best of the five — but you now know the one thing about it that might bite, before you order anything.
Controls
Task
| Control | Default | What it changes |
|---|---|---|
| Design task | Design new pair | Design new pair, Design with existing primer (supply one primer and the partner is designed), or Sequencing primers (walk) across the region |
| Template source | Open sequence | Open sequence, Current selection, or Pasted bases |
| Template bases | empty | The DNA to design on, when the source is pasted bases |
| Forward primer (5'→3', optional) · Reverse primer (5'→3', optional) | blank | With Design with existing primer: the primer you already have. Leave one blank and it is designed against the other |
Region & product
| Control | Default | What it changes |
|---|---|---|
| Product size | 300–700 bp | The amplicon length window the scan searches within |
| Number of pairs to generate | 5 | How many ranked pairs the table returns |
| Repeat library (mispriming) | None | Screens each annealing footprint against a repeat library (Human (repeats), Rodent (repeats), Drosophila (transposons)), so a primer sitting in a repetitive element is flagged before you order it |
| Included region · Range (1-based, inclusive) | whole sequence | An optional span every primer must stay inside |
| Target to flank · Target range (1-based, inclusive) | none | An optional span the amplicon must cover, with no primer sitting on top of it |
Primer characteristics
| Control | Default | What it changes |
|---|---|---|
| Length | 18–27 nt | The primer-length window |
| GC content | 40–60% | The GC window |
| Target Tm | 60 °C | Each primer is grown or shrunk to hit this melting temperature |
| Tm window | 57–63 °C | How far a primer's Tm may sit from the target |
Known SNPs
| Control | Default | What it changes |
|---|---|---|
| SNP set | Common (dbSNP 155) | Which variants count as known: Common (dbSNP 155), All of dbSNP 155, or ClinVar (dbSNP 155) |
| Avoid known SNPs | off | On, pairs with a primer on a SNP in the set are set aside, as Primer-BLAST's "Primer binding site may not contain known SNP" does. Off, the SNPs are flagged on each primer instead |
Specificity — Pairs to check (default 5) is how many of the top pairs are searched against the genome. At most 14: EMBL-EBI takes a batch of 30 searches, and each pair can need two plus one for the template.
Tails — 5-prime non-annealing sequence prepended to either primer. Binding coordinates, Tm and specificity stay on the annealing footprint; the structure numbers move to the full oligo.
Melting temperature and conditions — the shared conditions described in Melting Temperature: model, buffer, strand concentration, additives. These are the conditions the search runs under, not just the display, and they now also drive the structure measurements. The panel can detach onto its own conditions with an explicit override.
Scoring weights — one weight per penalty category (Tm deviation, pair ΔTm, GC, length, each structure class, 3-prime stability, poly-X, dinucleotide repeats, GC clamp, specificity, repeat library). Set a weight to zero and that property stops affecting the order.
Mispriming library — screen the annealing footprint against a repeat library, so a primer sitting in a repetitive element is flagged before you order it.
Primer Check — paste any primer and see its 3-prime-anchored binding sites on the open molecule with confidence tiers, strand, position, percent identity and mismatch count. This is a mismatch-tolerant scan and deliberately answers a different question from the design-time specificity check.
Algorithms you can choose
Melting temperature is the choice that changes the search, not just the readout: nearest-neighbour models (Allawi & SantaLucia 1997, SantaLucia & Hicks 2004, Sugimoto 1996, Breslauer 1986), the NEB model, the GC formulas and the Wallace rule, each with its own salt-correction handling. The primer search is nearest-neighbour by nature, so if you pick a GC or Wallace model the panel says in place that the search ran under a nearest-neighbour model while the display shows yours, rather than silently searching under one model and printing another.
Secondary structure is not a choice — there is one right answer here and it is primer3’s thal.
Offering a second, weaker structure model would only let you pick a number that disagrees with the
tool everyone checks against.
The science
Melting temperature is nearest-neighbour thermodynamics: stacking enthalpies and entropies per dinucleotide, plus initiation terms, plus salt and additive corrections. The full treatment, with what each correction contributes, is on Melting Temperature.
Hairpins and dimers come from a thermodynamic alignment — a dynamic program over the same nearest-neighbour parameters that finds the most stable structure the oligo can form, whether folded on itself or paired with another. Each structure is reported as a free energy and as the temperature at which it melts, and it is the melting temperature that the limits are defined on:
| Structure | Melts above | Why it matters |
|---|---|---|
| Hairpin | 24 °C | A folded primer is not available to anneal |
| Self-dimer, anywhere | 45 °C | Primers consumed pairing with each other |
| Self-dimer, 3-prime end paired | 35 °C | This one extends — it makes a dimer band |
| Cross-dimer, anywhere | 45 °C | The two primers consuming each other |
| Cross-dimer, 3-prime end paired | 35 °C | The classic primer-dimer product |
The 3-prime rows are measured in both directions, because the engine anchors only the first oligo’s 3-prime end, and the primer that extends might be the other one.
3-prime end stability is a different calculation and, confusingly, runs the opposite way. It is the nearest-neighbour stability of the last five bases treated as a perfect duplex, reported as a positive number where larger means more stable, and the default limit of 9.0 kcal/mol is a ceiling: an over-stable 3-prime end anchors at partly-matched sites and extends there, which is the classic mispriming mechanism. A weak 3-prime end is not the problem; an over-strong one is.
Two details worth knowing if you compare numbers with another tool. The calculation includes a correction for self-complementary ends that some implementations omit — worth 0.43 kcal/mol, and it applies exactly to the ends most likely to dimerise. And structure free energies depend on the buffer: change the salt in the conditions section and these numbers move, as they should.
Provenance of correctness: the melting-temperature engine is checked against Biopython and pydna; the structure engine is checked against primer3’s own output, byte for byte, over vector sets that cover every parameter in the tables rather than a sample of them — 784 vectors for the 3-prime stability calculation alone, including every dinucleotide, every four-base combination, and the degenerate and invalid inputs.
Shared with other tools: Melting temperature compares how every tool that does this chooses its method.
Sequencing walks
The Sequencing primers (walk) task answers a different question from the other two: not "which pair amplifies this", but "which primers do I need to read all of this, and will they actually cover it?"
The two numbers that decide a walk
A sequencing reaction does not read forever, and it does not start reading where the primer sits. Both facts set the spacing, and both are controls here rather than assumptions:
- Usable read length — how much trustworthy sequence one reaction returns. The default is 800 bases: the conservative end of the 800–900 that a university sequencing core publishes for the capillary instrument it runs. Your own facility publishes its own figure, and that is the one to put in.
- Unreadable start of a read — the same guide states that the quality of the first 25 to 35 bases is expected to be poor. So each primer is placed that far before the first base you need, and the default is 35. This is the mistake the control exists to prevent: a primer sitting exactly at the base you want to start reading will not read it, and the run comes back looking like a failure when the design was the problem.
- Overlap between reads decides whether your reads can be assembled. Reads that merely abut cannot be joined with confidence; overlap is what makes a contig. Default 100 bases.
- Both strands walks the reverse strand independently, so every base is read from both directions. That is what a sequencing facility means by covered, and it is the expectation for anything you intend to deposit or publish. Leave it on unless you are doing a quick check.
Read the coverage, not just the primer list
After a run, the Coverage readout states what the walk delivers over your region:
- whether every base is read, and if not, exactly which stretches are not — with coordinates, so you can raise the read length, lower the overlap, or place one primer by hand;
- which stretches are read from one direction only. This is usually the two ends of the region, where the walk runs out of template to place the opposite primer, and it is normal — but you should know it rather than discover it when a base call is ambiguous;
- any anchor where no primer could be designed at all, with the reason.
A list of primers with no coverage statement looks finished and tells you nothing about whether the job is done. On a 4.4 kb plasmid the default settings give 14 primers, full coverage, and the first 60 and last 55 bases read from one direction — which is the honest answer, not a complete one.
Pitfalls
- A walk primer that binds twice ruins its read. Each primer's binding-site count is reported; anything above one gives a mixed trace, which is the commonest sequencing failure that the sequence itself could have predicted.
- Do not set the read length from what your instrument can do. Set it from what your samples reliably give. An optimistic read length produces a walk with gaps that only appear as poor-quality tails after you have paid for the reactions.
- Sending primers off is the point, so name them by direction. Added to the map, walk primers
carry their walk names (
F1,R2, …), because "primer 7" does not tell you which way the read runs.
Limitations
- Structures are limited to 60 bases. A longer oligo gets no structure numbers, and the panel says so rather than showing a clean-looking blank.
- Bulge loops and coaxial stacking are not modelled by the structure engine, which finds gapless alignments. This is primer3’s own limitation, not an approximation added here.
- A melting temperature below zero is a real result, not a glitch. It means the structure is so weak it does not exist at any working temperature. You will see values like −49 °C on a clean primer; that is good news.
- Specificity here is against the sequences you have open, plus an optional repeat library. A primer unique in your plasmid may not be unique in a genome; the two questions are answered by two different searches, and both are one click away (see below).
- The ranking is a judgement, not a measurement. The score combines real measurements under weights that are defaults, not truths. Two pairs one point apart are not meaningfully different; read the columns.
- Numbers may differ slightly from primer3web. primer3web and
ntthalship an older release of the structure engine than the one used here; on a few percent of primer-length oligos the two disagree about which structure wins. That is a version difference, not an error, and the panel states which engine it is.
Two specificity questions, and they are not the same search
Does this primer anneal anywhere else on my construct? and does it anneal anywhere else in the genome? look like one question and are answered by different algorithms over different data. The panel gives each its own control on every designed primer.
On the open molecule — the magnifier. A 3′-anchored binding scan over the sequence in front of you, weighting identity towards the 3′ end because that is the end that has to be paired for a polymerase to extend. A 5′ cloning tail therefore lowers a site's identity rather than making it vanish, which is what you want: the tail is not supposed to anneal. This runs locally and instantly, and it is the check that catches the ordinary cloning failure — a primer that also sits in the backbone.
Against a database — the globe. This adds the primer to the map and hands it to BLAST as its own query, so you can search it against ENA, a genome, or any database the service offers. The primer goes out as the oligo you would order: a reverse primer is submitted reverse-complemented, not as the plus-strand span it sits on, because that is the molecule whose off-targets you are asking about.
Set the word size before you read the result, and this is the pitfall that matters. BLAST finds alignments by first finding an exact word shared by query and subject. At the general-purpose default of 11, a 20-base primer can only turn up off-targets that share an exact 11-base stretch with it — and a primer that mis-primes through a 9-base 3′ match, which is a completely ordinary way for a PCR to fail, produces no seed at all. The search comes back empty, and an empty result looks exactly like a specific primer. NCBI's own Primer-BLAST searches oligos at word size 7 for this reason. The panel warns you before the run, next to the target, whenever the word size would under-report; lower it and the warning goes away.
Two more things worth knowing when you read the hits: short queries need a generous expect value (the default is tuned for genes, and a 20-mer's best legitimate hit can look statistically unremarkable), and a hit is only worth worrying about if the mismatches are at the 5′ end of the primer. A partial match with three mismatches in the last four bases will not prime.
Export
Ranked pairs export as CSV — one row per pair carrying every measurement for both primers separately, including 3-prime stability, each structure’s free energy and melting temperature, poly-X, the GC clamp and uniqueness. A pair exports as FASTA. The product can be opened as a new project or exported as GenBank with the primers annotated. Individual primers can be added to the map as annotations, or saved into the Primer Library for ordering.
Provenance
A design run records its constraints and the conditions it ran under, so a pair in your library can be traced back to the buffer and model that produced its Tm. Primers written to the map carry their binding coordinates and strand as real annotations.
To cite the method: melting temperatures are nearest-neighbour calculations under the model and buffer you selected; secondary-structure free energies and melting temperatures are from primer3’s thermodynamic-alignment engine; 3-prime end stability is primer3’s nearest-neighbour end-stability calculation over the terminal five bases.
Screenshots
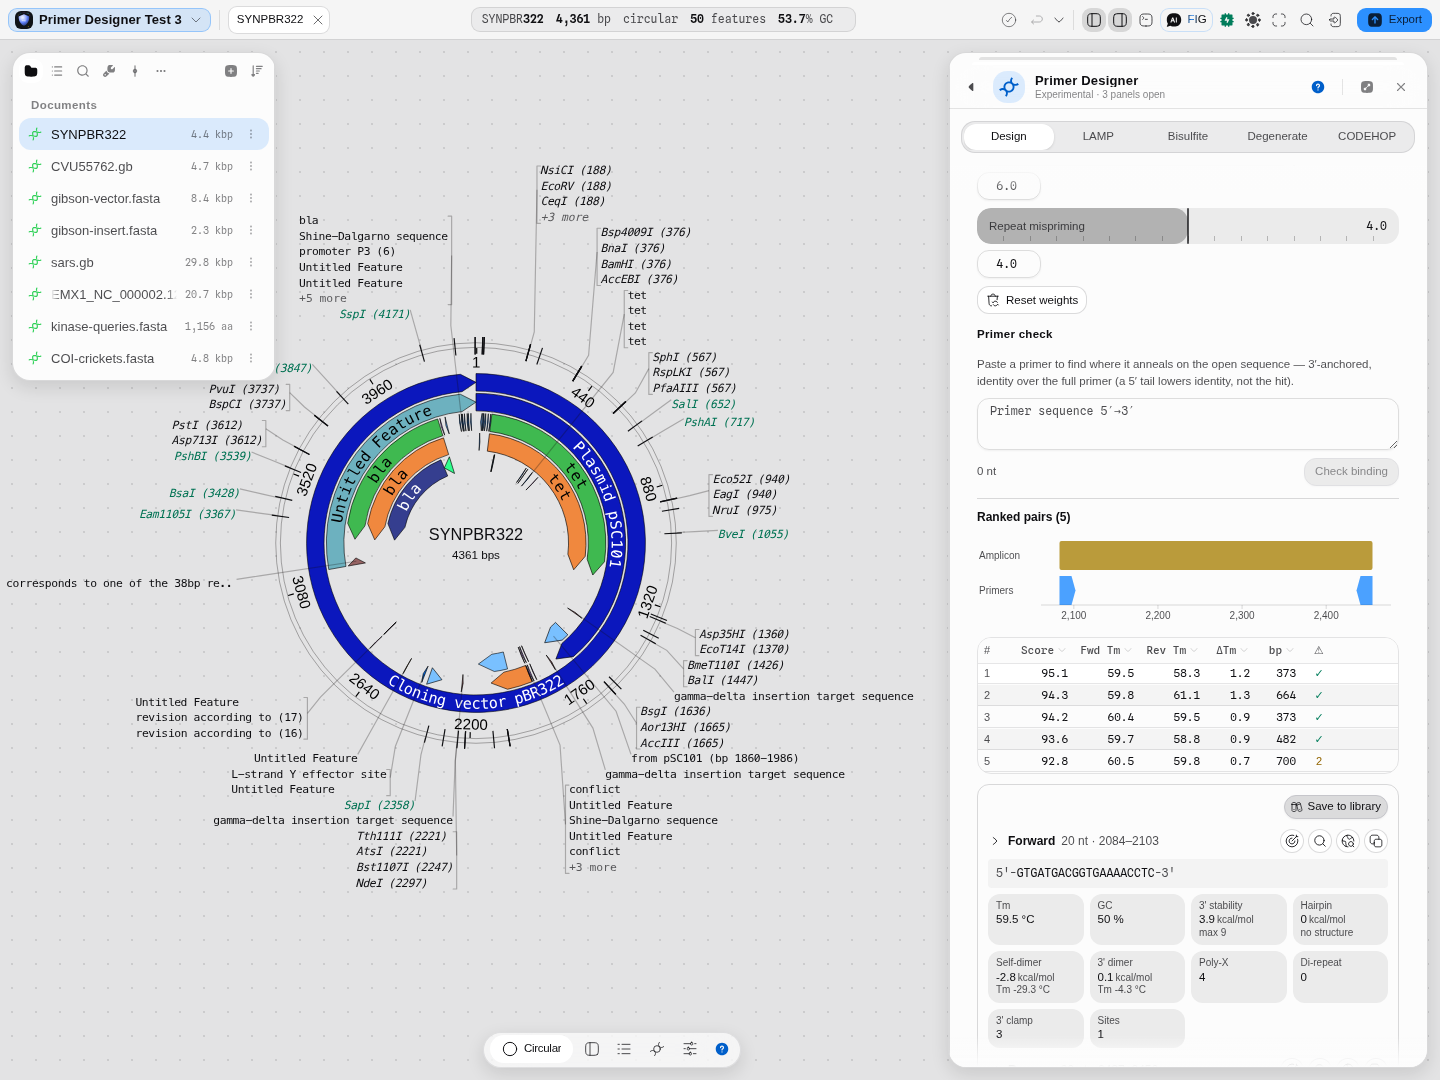 The panel as it opens.
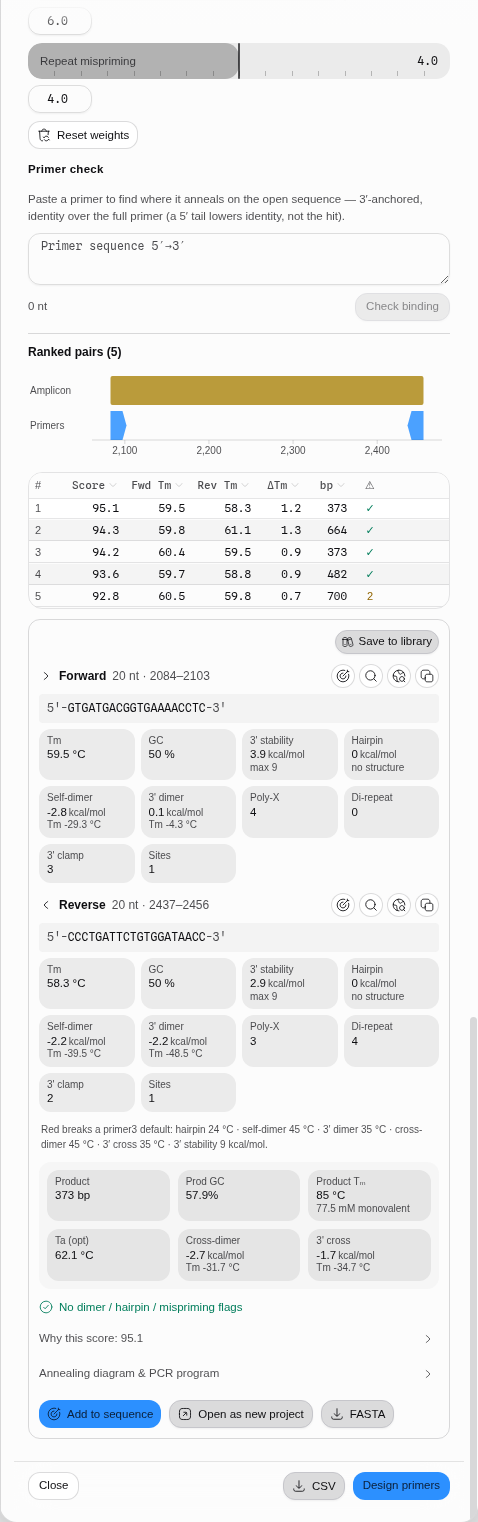 After a run, with real results on screen.
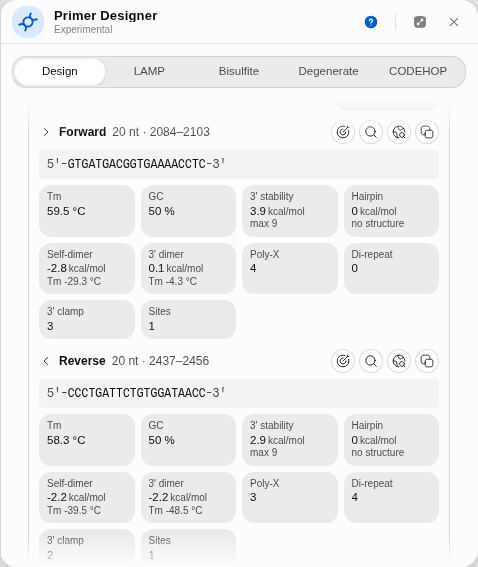
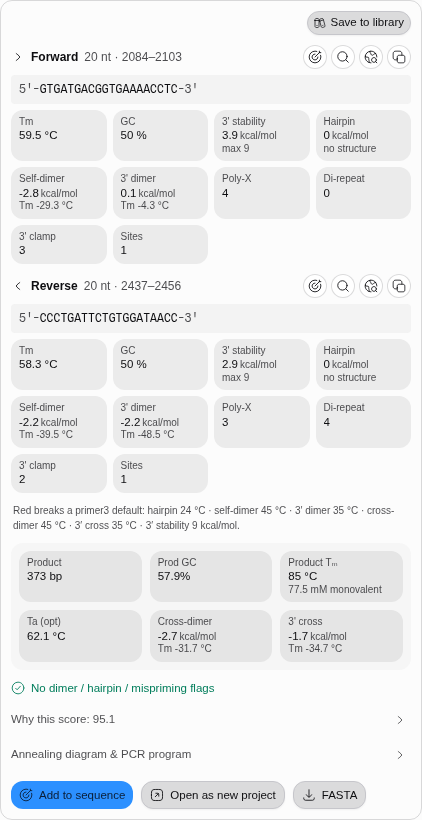 Every measurement for both primers of the top-ranked pair. Each structure free energy carries the
temperature that structure melts at; the primer3 limits are stated once beneath the pair; and the
warnings name the measurement that broke one — here, both hairpins melting above 24 °C.
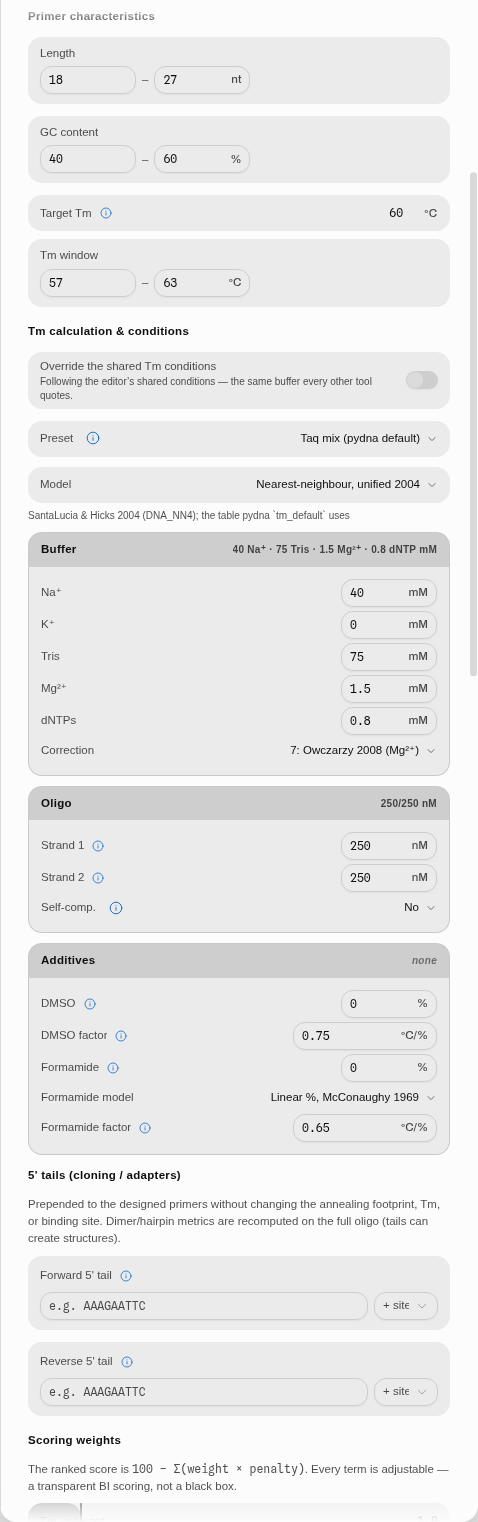 Scrolled, showing the controls below the fold.
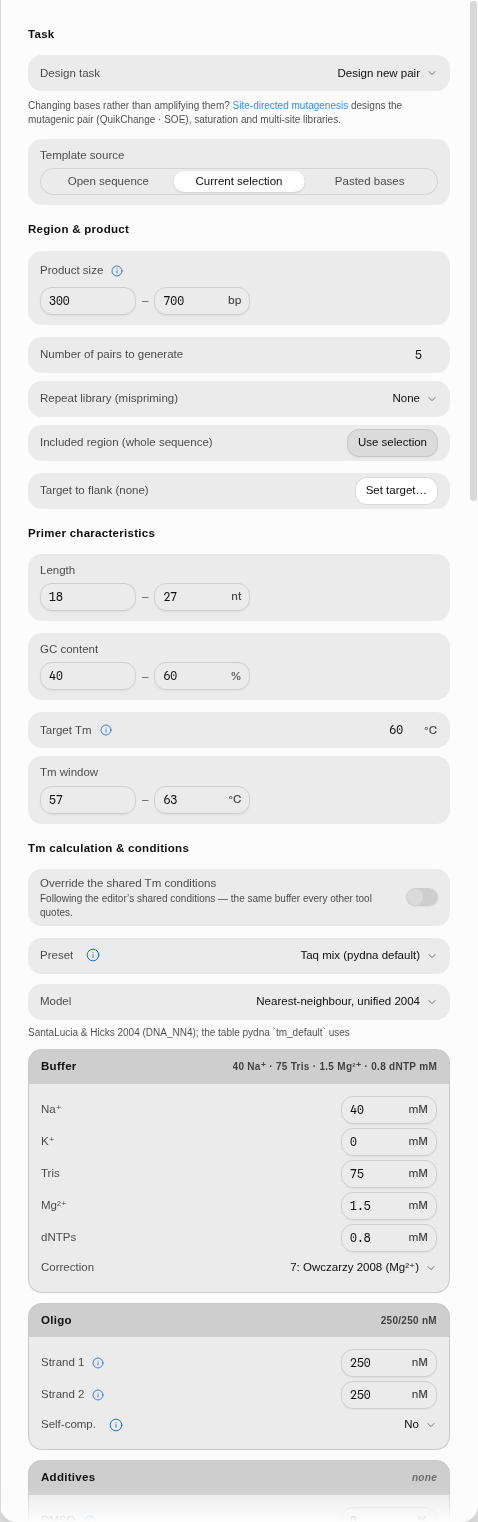 The current selection tab.
Related
Feeds it: a selection or feature on the canvas · Melting Temperature, which owns the conditions the search runs under.
Follows it: PCR Simulation for the product and cycling program · Primer Library to store and order the oligos · Digest & Gel to see the band.
Alternatives: Primer Library’s Check and Screen tabs when you already have the primers · qPCR Design for probe-based assays · Site-Directed Mutagenesis for mismatch-carrying primers.
In this group: LAMP primer set · Bisulfite methylation primers · Degenerate primers from an alignment · CODEHOP hybrid primers from a protein alignment · Primer Library · PCR Simulation · Fusion PCR · Multiplex PCR · qPCR Design · Digital PCR · Amplification Curves → Cq · Melt Curves → Tm · Droplet gating → concentration · Droplet classification · Melting Temperature
Multi-site mutagenesis
Name the substitutions you want anywhere in a gene and get the mutagenic oligos for them, designed for the one-tube multi-site protocol.
LAMP primer design
Design a complete loop-mediated isothermal amplification set — F3, FIP, BIP, B3 and the two loop primers — against a region of an open sequence, under the criteria published by the people who invented the method.